← All work
2025 · Service
Course RAG
Retrieval over 40k pages of course material with hybrid search and a reranker, served under 500 ms.
Problem
Students asked the same questions across lecture notes, slides, and forum threads, and keyword search returned the wrong lecture half the time.
Approach
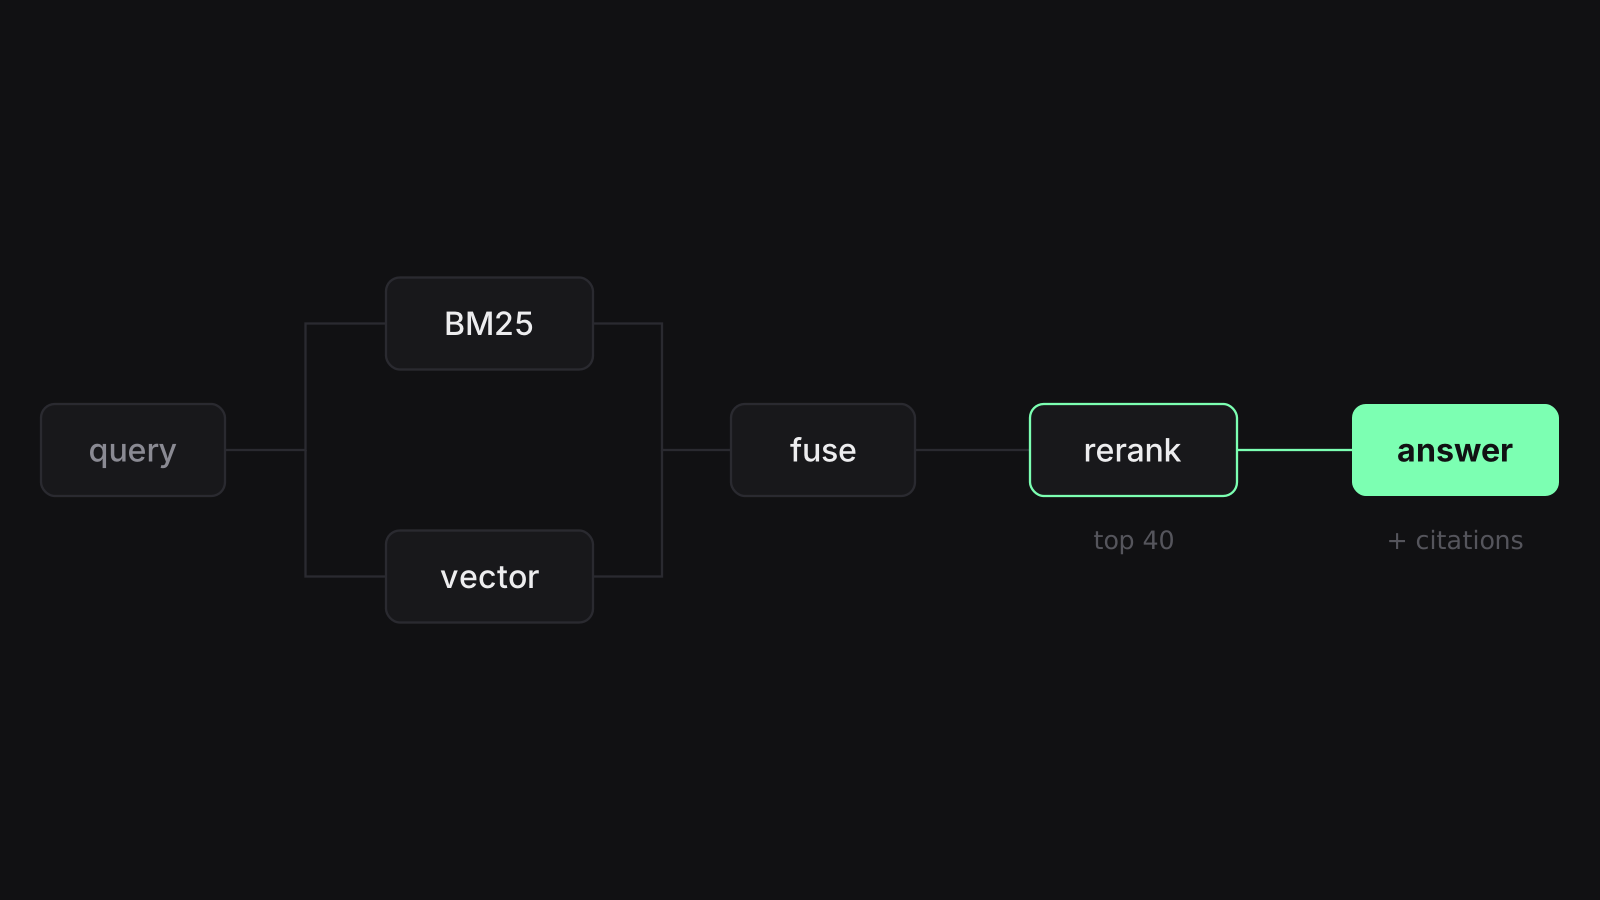
Chunk by heading, embed with a small open model, and combine BM25 with vector search using reciprocal rank fusion. A cross-encoder reranks the top 40 before the answer is generated with citations.
create table chunks (
  id        bigserial primary key,
  doc_id    text not null,
  heading   text,
  body      text not null,
  embedding vector(768),
  tsv       tsvector generated always as (to_tsvector('english', body)) stored
);
create index on chunks using hnsw (embedding vector_cosine_ops);
create index on chunks using gin (tsv);Architecture
  query ──► bm25 ─┐
                  ├─► rrf ──► reranker (top 40) ──► generator ──► answer + cites
query ──► hnsw ─┘Results
- Answer accuracy on a 200-question held-out set rose from 61% to 84%.
- Switching from a hosted embedding API to a local model cut monthly cost 40%.
- p95 end-to-end latency: 410 ms at 200 QPS on one 4-vCPU box.
What I'd do next
Query rewriting for follow-up questions and a feedback loop that promotes chunks users mark as helpful.