2025 · CLI Tool
Agent Harness
A test harness for LLM agents that replays real tool-call traces and scores them before you ship.
Role
Solo · design + build
Timeline
Mar — Jun 2025
Stack
Python, LangGraph, Postgres, Typer
Problem
Agents fail in ways unit tests don't catch: a tool returns a slightly different shape, the model picks the wrong tool on the third turn, or a retry loop burns the token budget. Teams found this out in production, not in CI.
Approach
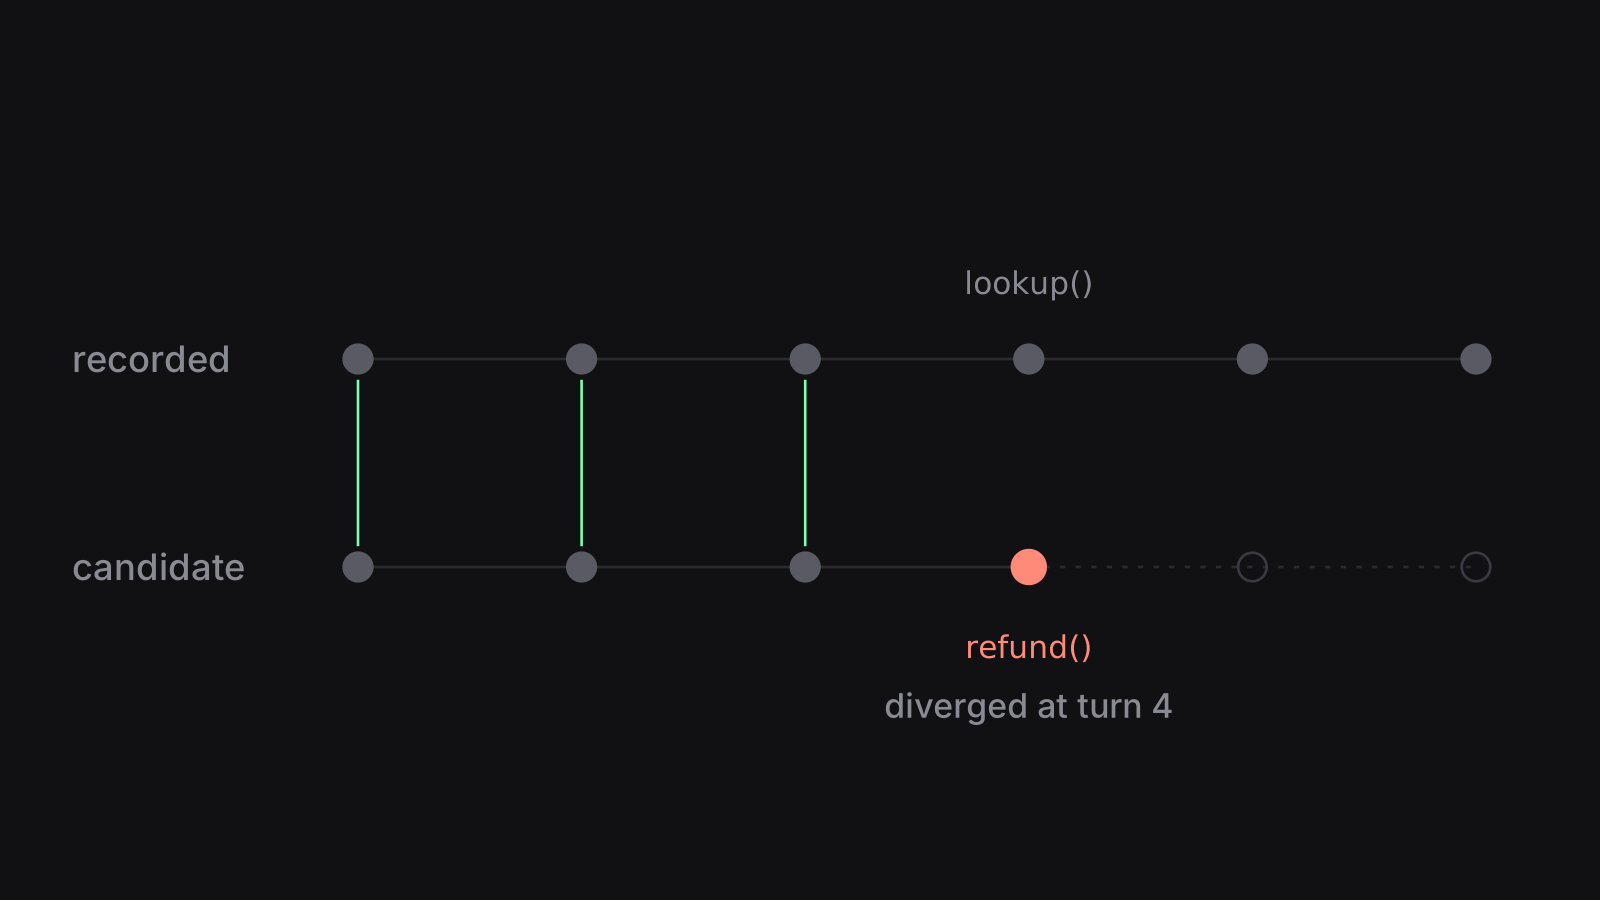
Record every tool call from a real session as a trace, then replay it against a candidate prompt or model with the tools mocked. Score each replay on three axes — task completion, tool-choice accuracy, and cost — and fail the build when any regresses beyond a threshold.
from harness import Trace, Scorer, replay

trace = Trace.load("traces/refund-flow.jsonl")
result = replay(trace, model="claude-sonnet-5", tools=trace.mocked_tools())

Scorer(thresholds={"completion": 0.95, "cost_delta": 0.10}).assert_ok(result)Architecture
  session ──► tracer ──► traces/*.jsonl
                              │
                              ▼
  CI ─────► replay ──► mocked tools ──► scorer ──► report.md
                              ▲
candidate model / promptThe tracer is a thin middleware on the tool router. Replay is deterministic because tool outputs come from the trace, not the live system; only the model's decisions vary.
Results
- Caught 3 regressions before release that had slipped through the existing unit suite.
- Task failure rate on the 120-scenario suite dropped from 21% to 13%.
- Full suite runs in under 4 minutes on a laptop.
What I'd do next
Add a diff view that shows where two runs diverged turn-by-turn, and support for multi-agent traces where sub-agents have their own tool routers.